A WAF false positive is a legitimate request that a web application firewall blocks, challenges, or flags because it looks like an attack. A CMS editor saving HTML, a search box receiving the word “union”, or a redirect link containing :// can all trip a rule and send a 403 to a real customer. The fix is rarely switching rules off; it is finding the exact rule, field, and path, then writing the narrowest exception. This guide covers why a WAF false positive happens, what a healthy false positive rate looks like, how to detect and troubleshoot one, and how to tune managed rules safely. It starts with the part most teams get wrong: the four possible outcomes.
Key Takeaways
- A WAF false positive is a legitimate request the firewall blocks, challenges, or flags as malicious; a false negative is an attack it lets through.
- Most false positives come from generic rules meeting valid but unusual input: HTML in CMS fields, SQL keywords in prose, URLs in query strings, encoded tokens, and oversized request bodies.
- In a peer-reviewed lab test of ModSecurity with OWASP CRS, paranoia level 1 produced zero false positives, while levels 2 to 4 averaged 14.90 to 17.40 per test run.
- A WAF false positive rate only means something next to the detection rate, because a WAF that blocks nothing scores a perfect zero.
- Troubleshooting works best as a fixed loop: trace the block ID to the rule, the matched field, and the path, then exclude only that combination.
- New managed rules belong in count or detection-only mode first, with blocking switched on only after scoped exclusions clear the noise.
- Disabling a rule globally or dropping the paranoia level is the bluntest fix available and should be the last resort, not the first.
WAF False Positive vs False Negative
Each WAF decision results in a true positive, true negative, WAF false positive, or false negative. A WAF false positive occurs when the firewall treats a legitimate request as malicious. The user has not made an error; their input matched a pattern that the firewall associates with an attack.
A cloud web application firewall operates in front of your application, inspecting headers, cookies, query strings, and request bodies based on WAF rules that describe attack behavior. Each decision falls into one of four outcomes, but only true positives and true negatives are correct results.

The two errors have opposite impacts. A WAF false positive results in losing a real user, a sale, or an API call. A false negative leads to a security breach. WAF tuning aims to lower both the WAF false positive rate and false negatives simultaneously, which is more challenging than reducing only one to zero.
| Aspect | False positive | False negative |
|---|---|---|
| What happens | Legitimate request is blocked or challenged | Malicious request reaches the application |
| Who notices first | Customers, support, partner integrations | Often nobody, until an incident |
| Typical signal | 403 spikes on a single endpoint or form | Suspicious data access in app or database logs |
| Business cost | Lost conversions, broken workflows, tickets | Data exposure, downtime, compliance findings |
| Usual fix | Scoped rule exclusion or input handling change | New rule, stricter level, or code fix |
Two real cases show how ordinary the trigger usually is. The OWASP CRS documentation describes a WordPress post submitted with an <h1> heading in the wp_post parameter: at paranoia level 2, an XSS rule fires on the HTML tags even though WordPress sanitizes them safely. AWS describes a similar case in its managed rules guidance, where legitimate redirect requests were blocked by the GenericRFI_QUERYARGUMENTS rule because the query string contained ://, the same characters a remote file inclusion attempt uses.
Those two examples share a root cause, and once you see it, most false positives stop looking random.
Why Do WAF False Positives Happen?
WAF false positives occur because most WAF rules are generic. These rules describe attack patterns instead of what your application expects, so valid input that looks like an attack can trigger a block.
This process follows the negative security model. Signature and pattern rules define what is forbidden, and any matching input is treated as hostile. The CRS project clearly states in its documentation that a new deployment lacks context about the web services it protects. For example, it does not know your rich text editor should accept markup.
Anomaly scoring softens this, since one weak match rarely blocks on its own, and you can read how the OWASP Core Rule Set scores requests in detail elsewhere. But scoring does not eliminate the main problem. It is also why teams that run custom WAF packages begin with application-specific WAF rules and exclusions instead of relying on a generic baseline.
In real-world cases, WAF blocking legitimate traffic usually traces back to a few input types:
- Rich text and HTML input. CMS editors, email template builders, and comment fields that allow markup trip cross-site scripting rules (the CRS 941 family).
- SQL-like language. Product names, legal clauses, and search terms containing words such as select, union, or a stray apostrophe look like injection. Rules tuned to catch blind SQL injection probes hunt for boolean and timing fragments that normal sentences can contain.
- URLs inside parameters. Redirect targets, OAuth callbacks, and webhook addresses match remote file inclusion patterns.
- Encoded and structured payloads. Base64 blobs, JWTs, serialized JSON, and long random tokens produce character mixes that rules read as obfuscation.
- Large request bodies. Bulk APIs and file uploads hit size restriction rules; AWS names SizeRestrictions_BODY as a common source of false positives on data-heavy endpoints.
- Aggressive configuration. High paranoia levels, low anomaly thresholds, and several managed rule groups stacked on the same traffic multiply the chances of a match.
What most people miss is how concentrated the problem is. AWS lists three recurring patterns in its own troubleshooting guidance: CMS platforms that accept HTML trigger XSS rules, database administration tools trigger SQL injection rules, and large API payloads trigger body size rules. False positives rarely spread across a whole site. They pile up on a handful of forms and endpoints, which is exactly what makes them fixable.
Knowing the causes is half the picture. The other half is knowing how many false positives are normal before you start tuning.
What Is a Good WAF False Positive Rate?
A tuned production WAF should block legitimate requests so infrequently that every block can be reviewed individually. Published tests indicate this means well below 1% of legitimate traffic. Default WAF configurations can have a much higher WAF false positive rate.
The WAF false positive rate measures the proportion of legitimate requests blocked by the firewall. You calculate it as false positives divided by all legitimate requests. This metric alone is misleading. A WAF that allows every request achieves a perfect WAF false positive rate but provides zero protection. The WAF false positive rate only has value when considered alongside the detection rate.
Check Point conducted one of the few large-scale comparative tests by running over 1 million legitimate requests and 74,000 malicious payloads against 14 different WAF products. Check Point both executed the test and ranked its own product first, so the results are best viewed as directional, not neutral. Even so, the range in WAF false positive rates is significant:
| WAF tested | Detection rate | False positive rate |
|---|---|---|
| Check Point CloudGuard WAF | 99.5% | 0.56% |
| Microsoft Azure WAF | 97.5% | 54.4% |
| Google Cloud Armor | Strong (not quantified in summary) | 56.9% |
| AWS WAF | Comparatively low (not quantified in summary) | 6.04% |
| Cloudflare WAF | 63.46% | Near zero (not quantified in summary) |
A near-zero WAF false positive rate may seem ideal, but in the same test, a product with almost no false positives only detected 63.46% of attacks. Achieving low noise by sacrificing detection is not a valid strategy. Balanced accuracy, which averages the detection rate and the proportion of legitimate traffic allowed, offers a fairer measure of performance.

The strictness of WAF rules also impacts the WAF false positive rate. A peer-reviewed study in Engineering Proceedings tested ModSecurity 2.9 with OWASP CRS 3.3.7 as a reverse proxy. The researchers replayed 30 groups of legitimate requests, ranging from 10 to 300 requests, 20 times at each paranoia level.
Paranoia level 1 resulted in zero WAF false positives. At level 2, the average was 14.90 per run; at level 3, it was 17.40; and at level 4, it was 17.25. There was no statistically significant difference in false positive rates among levels 2, 3, and 4. In practice, the major increase in noise occurs once you move above PL1, so plan a tuning phase for any higher setting.
“the use of rule exclusion directives and fine-tuning remains essential”
A single metric on a dashboard provides limited insight. The real impact of WAF false positives becomes clear when you look at how they affect a team over time.
Why WAF False Positives Cost More Than a Few Blocked Requests
WAF false positives impact revenue at the time of the block, increase support workload afterward, and weaken security over time. When a WAF generates excessive noise, teams often switch it to log-only mode, reducing its effectiveness.
The first cost is direct. When a shopper encounters a 403 error at checkout, they usually abandon the purchase. The second cost comes from investigation. Without a block reference ID, support teams cannot match customer complaints to log entries, turning every incident into a manual search. Implementing custom error pages that show a block reference converts unclear complaints into actionable events.
The third cost is the most damaging. If a smoke detector triggers every time someone cooks toast, it will soon be disabled. Similarly, if a WAF blocks legitimate users too often, blocking gets disabled “temporarily,” and the firewall ends up serving only as a log file.
Some may think that blocking a few requests is a reasonable tradeoff for security. The real cost lies not in the few blocked requests, but in the policy decisions that follow. Scale is critical: at a 6.04% WAF false positive rate, as measured for one cloud WAF, a site with 1 million legitimate requests would block about 60,400 of them. For another WAF with a 54.4% false positive rate, it would block more real users than it allows.
Intrusion prevention systems faced similar challenges. The main difference between WAF and IPS is the amount of application context each provides when making decisions. More context leads to fewer false alarms and reduces Web Application Firewall false positives.
The positive aspect is that WAF false positives leave clear traces. The next section explains how to identify them.
How to Detect a WAF False Positive in Your Logs
WAF false positive detection starts with pattern matching in your logs: false positives cluster on one rule, one parameter, and one path while coming from many ordinary clients, whereas real attacks look scattered and probing.
Attack traffic behaves like a burglar testing every door. It rotates payloads, walks through parameters, and usually comes from a small set of scanners or botnets. False positive traffic behaves like a crowd using the same door correctly: same endpoint, same field, same rule, many different people.
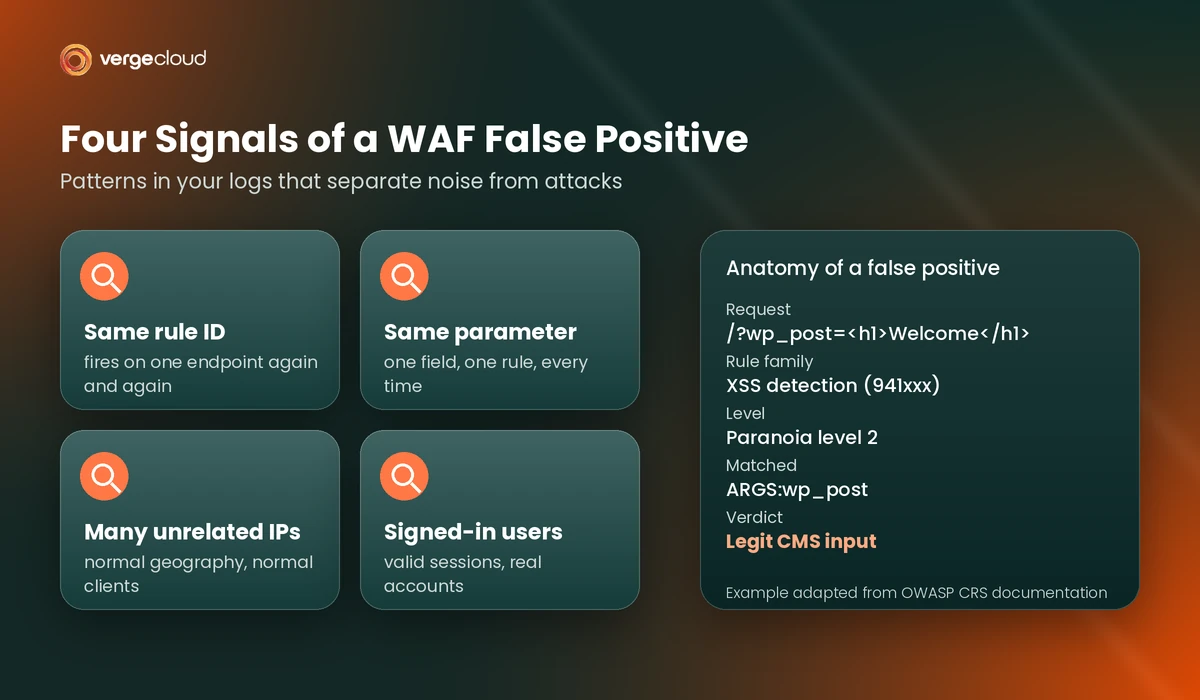
- Same rule ID, same path. One rule firing hundreds of times on /editor or /checkout, and almost nowhere else.
- Same matched variable. The log shows the identical field (for example ARGS:content) every time.
- Many unrelated clients. Normal geography, normal user agents, and no sign of scanning behavior.
- Authenticated sessions. Blocks landing on logged-in users with valid session cookies are a red flag for a rule problem.
- Matching support tickets. Complaints that line up in time with a new rule, a managed rule update, or an application release.
Client signals help separate the two. JA3 fingerprinting identifies the TLS client behind a request, so a block carrying the same fingerprint as your own mobile app’s normal traffic points at the rule, not the visitor. AWS gives similar advice in its guidance for moving managed rules from count to block: check whether source IPs belong to trusted internal systems or partners, whether URIs map to real endpoints, and what the matched data field actually contains.
For JSON-formatted WAF logs, a one-line query surfaces the hot spots. Field names vary by product, so adjust them to your schema:
# Top rule + path + field combinations among blocked
# requests

jq -r 'select(.action=="BLOCK") |
[.rule_id, .uri, .matched_var] | @tsv' waf.log \
  | sort |
uniq -c | sort -rn | head -20
Add a unique request or block ID to every blocked response and to the matching log entry. It cuts triage from searching timestamps to a single lookup, and it is the first thing to ask for when a user reports a block.
Spotting a suspected false positive is the easy part. Proving it and fixing it without opening a hole takes a repeatable process.
WAF False Positive Troubleshooting in Six Steps
WAF false positive troubleshooting uses a repeatable process: capture the block, trace the rule, inspect the matched data, classify the request, write the most targeted exclusion, and verify the result. Skipping steps often leads teams to disable entire rule groups unnecessarily.
- Capture the evidence. Gather the block ID, timestamp, URL, and the specific action the user performed. If possible, reproduce the issue in a staging environment.
- Trace the rule. Search the WAF logs for the block and document every rule that matched, not just the final blocking rule. With anomaly scoring, multiple low-severity matches can combine to cause a block.
- Inspect the matched data. Identify the variable (such as ARGS, header, cookie, or body) and the exact value fragment that triggered the WAF false positive.
- Classify the request. Determine if the input is legitimate for that field. Exclude parameter tampering, where a client alters values the application should control. A WAF false positive on a hidden price field is often actually a true positive.
- Write the narrowest exclusion. Exclude only one field from one rule on one path. Do not remove the rule globally.
- Verify and document. Replay the request to ensure the block is resolved. Confirm that attack payloads against the same field are still blocked. Record the exclusion with an assigned owner and a documented reason.
For ModSecurity or Coraza running CRS, a precise exclusion targets rule 941100 (XSS detection via libinjection) and prevents it from inspecting only the post content field on the WordPress editor path. All other rules continue to inspect the field:
You may think allowlisting a user’s IP address is a faster solution. While it is quicker, it is usually the wrong approach. Custom IP lists are appropriate for trusted partners, internal scanners, and uptime monitors with static addresses, but not for customers whose IP addresses change or whose network neighbors could be attackers.
The skill behind writing exclusions lies in step five. The next section compares WAF rule tuning methods, from broad to targeted.
WAF Rule Tuning Techniques, From Blunt to Precise
Effective WAF rule tuning applies the narrowest exception needed to resolve the WAF false positive. Any broader exception weakens protection for traffic that never caused issues.
Treat WAF tuning like surgery, not amputation. Disabling a rule sitewide may fix one issue but also removes protection from the login page, API, and search box. Excluding a single field on a single path solves the targeted issue without affecting other areas.
| Tuning technique | Scope of change | Coverage lost | Use it when |
|---|---|---|---|
| Disable the WAF or switch to log only | Entire site | Everything | Never as a fix; only for an emergency rollback |
| Disable a rule site-wide | One rule, all paths | That rule everywhere | The rule is broken for your whole stack |
| Lower paranoia level | Many rules, all paths | Stricter detections | You moved up a level without a tuning phase |
| Raise anomaly threshold | Scoring, all paths | Single-match blocking | Many low-severity matches stack on normal traffic |
| Disable a rule on one path | One rule, one path | That rule on that path | A path legitimately needs the flagged behavior |
| Exclude one field from one rule | One rule, one field, one path | Almost none | The default choice for most false positives |
| Allowlist a trusted client | Specific IPs or clients | All inspection for them | Fixed-address partners, scanners, monitors |
The OWASP CRS project frames the whole discipline in a single line:
“False positives need to be tuned away by writing rule exclusions”
Raising the anomaly threshold is often suggested as the quick fix. Yes, it cuts noise, but it cuts it for every endpoint at once. In CRS, a critical match adds 5 points and the default inbound threshold is 5, so moving the threshold to 10 means one clear SQL injection pattern no longer blocks by itself anywhere on the site.
Two shortcuts are worth knowing. First, the CRS project maintains official rule exclusion plugins for WordPress, Drupal, Nextcloud, DokuWiki, and cPanel, which pre-exclude known-good behavior for those platforms. Second, some “false positives” are really abuse controls in the wrong layer. Repeated login attempts or aggressive polling are better handled with rate limiting than by loosening injection rules until the bursts pass.
Self-managed rule sets give you full control over all of this. Managed rule groups from a provider add a twist: rules you did not write, updating on a schedule you do not control.
How to Tune WAF Managed Rules Without Losing Coverage
Tune WAF managed rules by running new rule groups in count mode, pinning their version, reviewing matches per rule and path, and overriding only the specific rules that misfire.
Managed rules are maintained by a provider’s threat research team, which is their strength and their risk. They update quickly as new attacks appear, and an update can change behavior on traffic that was clean yesterday. The tuning tools differ by platform, but the ideas match.
- Count first. Deploy the rule group with actions overridden to count or detection only, so matches are logged but nothing is blocked.
- Review by rule and path. Rank matches by rule ID and endpoint for at least one full business cycle, including batch jobs, sales, and month-end runs.
- Exclude precisely. Add scoped exclusions or exceptions for verified false positives, one rule and one field at a time.
- Block and keep watching. Switch to blocking, then re-review after every managed rule version change.

Platform specifics follow the same pattern. AWS WAF lets you override individual managed rules to Count, attach labels to matches, and write a custom rule that blocks on the label unless an exception condition is met. It also supports scope-down statements and version pinning, and you can run two versions of the same rule group side by side, one counting and one blocking. Azure WAF offers detection and prevention modes plus exclusion lists at the rule, rule group, and policy level. Cloudflare’s documentation recommends disabling a single misfiring rule rather than the whole ruleset.
Body inspection limits deserve a special check. The Check Point test found that some WAFs stop inspecting oversized, padded payloads and let them through, while AWS and Azure took a restrictive approach that the report says may require extra exception handling for data-heavy applications. If you run bulk APIs, test large legitimate bodies on purpose.
The same monitor-first pattern applies to any reverse proxy WAF deployment: real traffic should reveal false positives before your users do.
Rules and exclusions are one approach. Scoring requests with machine learning is another, and it promises fewer false positives. The reality is more mixed.
Can WAF Anomaly Detection and Machine Learning Reduce False Positives?
Partly. WAF anomaly detection and machine learning scoring catch attack variants that signatures miss and let you set thresholds per endpoint, but they produce their own false positives and need the same exception workflow.
Machine learning models score requests on how likely they are to be malicious instead of matching a fixed string. Cloudflare’s WAF attack score, for example, rates each request from 1 to 99, where 1 means almost certainly malicious, and groups requests into classes from attack to clean. Research points the same way: the ModSec-Learn project showed that tuning CRS rule weights per application with machine learning can reduce false positives while keeping detection high.
Here is the contrarian part. A signature block tells you exactly which rule fired and on which field, so you can exclude it precisely. A model score often does not. When an ML engine blocks a legitimate request, the fix is usually a threshold change or a broad exception, which is closer to the blunt end of the tuning ladder. Explainability is not a nice-to-have in WAF operations; it is what makes a false positive fixable in minutes instead of days.
The strongest setups combine both. Signatures handle known attack classes with clear audit trails, scores flag unusual requests for review or challenge, and an edge security layer adds client reputation and behavior before a request ever reaches the origin. No single signal should carry the whole decision.
Whatever engine you run, the teams with the fewest false positives share a small set of habits.
WAF False Positive Mitigation Best Practices
Effective WAF false positive mitigation treats tuning as a continuous engineering process. Use baselines, regular tests, assigned owners, and scheduled review dates. Avoid treating it as a one-time setup task.
- Establish a baseline before blocking. Operate in detection-only mode for a complete business cycle, then set enforcement thresholds using observed scores from legitimate traffic.
- Test every change against real traffic. Maintain a collection of legitimate requests, such as editor saves, API calls, and uploads, and replay them after each rule or application update. The CRS project uses the go-ftw framework for regression testing of this kind.
- Handle exclusions as code. Store every exclusion in version control, including a ticket, owner, and review date. Unreviewed exclusions accumulate into silent vulnerabilities.
- Re-tune WAF rules after each release. New forms, API fields, or third-party scripts often introduce new WAF false positives.
- Keep each layer on its own job. Know where a WAF versus a network firewall draws its line, and leave volumetric floods to DDoS mitigation at the network edge instead of stretching WAF rules to absorb them.
- Measure both WAF false positive rate and detection rate. Track and review them together on a monthly dashboard.
Set an expiration date for every exclusion. When the date arrives, re-test the original WAF false positive against the current rule version. Managed rule updates often resolve the issue, allowing removal of the exclusion.
Two practical examples illustrate advanced WAF false positive mitigation. The CRS project offers platform-specific exclusion plugins so that common CMS behavior does not require manual exceptions. AWS allows teams to run both old and new managed rule versions simultaneously for comparison before switching. Both approaches focus on testing the tuning process, not just applying changes.
Final Thought on WAF False Positives
WAF false positives do not mean a web application firewall is failing. They indicate that generic rules encountered a specific application, and bridging that gap requires expertise in both areas. The goal is never to reach zero alerts. The objective is to have a WAF that blocks real attacks, allows legitimate users, and provides clear explanations for every decision so rare mistakes can be fixed quickly.
Begin in detection mode, measure WAF false positives and detection rates, and trace each block to the specific rule, field, and path. Always select the narrowest exclusion that addresses the issue. Teams that maintain this discipline keep their WAF in blocking mode, which is the only way to provide effective protection.
Common Questions About WAF False Positives
How often should WAF rules be re-tuned?
Review WAF rules after every application release that modifies input handling, after every managed rule version update, and on a set schedule such as quarterly. Re-test all existing exclusions at these times to prevent outdated exceptions from remaining in place.
Should I run my WAF in detection-only mode permanently to avoid false positives?
No. Detection-only mode is meant for tuning, not for ongoing operation. It logs attacks rather than stopping them, so keeping a WAF in this mode permanently provides visibility but not protection. Use detection-only mode for a full business cycle, fix issues it uncovers, and then enable enforcement.
Can WAF false positives block search engine crawlers?
Yes. If a crawler request triggers a rule, search engines will receive 403 errors and may remove affected pages from their index. Review WAF logs for blocked requests from known crawler IP ranges, and confirm crawler identity with reverse DNS instead of relying on the user agent string.